 Kexi's blog
Intro to Protocol Buffers (Protobuf)
Background
Protocol Buffers (a.k.a., protobuf) are Google’s language-neutral, platform-neutral, and extensible mechanism for serializing structured data. You define your data structure once in a .proto file, then use generated source code to easily read and write that structured data across different languages and platforms.
For example, a Java program on one platform can serialize data according to a .proto definition, and a Python application on another platform can deserialize that data and access specific values.
Unlike JSON, Protobuf encodes data in a compact binary format, making it much smaller and faster to serialize and deserialize. It enforces a strict schema, providing type safety and supporting forward and backward compatibility, so you can safely evolve your data structures over time.
Protocol Buffers is primarily a specification (or protocol) for serializing structured data, but it comes with multiple components that can make it feel like a library (
protoc= compiler that generates code based on the spec; Language-specific runtime = library to work with messages)Serialization is the process of turning a data structure into a sequence of bytes that can be transmitted. JSON, for example, serializes data as human-readable text.
Installing Protobuf
To install protobuf, you need to install the protocol compiler (used to compile .proto files) and the protobuf runtime for your chosen programming language.
- The Protobuf compiler (
protoc) is written in C++. For non-C++ users, the easiest way to install it is by downloading a prebuilt binary from the GitHub release page and adding it to your system PATH. - Each programming language requires its runtime library to work with the generated code. Some languages may also need additional plugins for code generation, e.g.,
protoc-gen-ts_protofor TypeScript. - The runtime library provides the functionality to serialize and deserialize messages. Without it, the generated code only defines the message structure and cannot encode or decode data. The runtime implements the actual logic for handling the Protobuf binary format.
Understanding .proto files
A .proto file defines the structure of data (like JSON schema) and optionally RPC services (like API endpoints). It tells Protobuf how to serialize and deserialize data.
With JSON, you often send ambiguous or non-guaranteed data. You may encounter a missing field, an incorrect type, or a typo in a key. With Protobuf, that’s impossible. Everything starts with a
.protofile that defines the structure of messages precisely.
// Define a message
message Person {
  string name = 1;  // field #1
  int32 id = 2;     // field #2
  string email = 3; // field #3
}

// Define a service (for RPC calls)
service PersonService {
  rpc GetPerson(GetPersonRequest) returns (Person);
}

// Another message used by the service
message GetPersonRequest {
  int32 id = 1;
}
A message defines a structured data type. Each field has a type (string, int32, bool, another message, etc.), a name, and a field number (= 1, = 2). Field numbers are unique identifiers used in the binary encoding to efficiently identify each field. Once a .proto file is published, do not change field numbers, as they ensure backward compatibility.
When Protobuf encodes data, it stores the field numbers rather than the field names. This allows older programs to safely ignore any new fields they don’t recognize while still processing the fields they do know.
Some keywords:
optional- field may or may not be presentrequired- field must be present (proto2 only, deprecated in proto3)repeatedmeans an array/list of valuesenum- defines enumerated valuesmap- key-value pairs (e.g.,map<string, int32>)package- namespace for your messages
A service defines RPC methods. Each rpc line defines one endpoint with input and output message types. It includes a method name, request message type, and response message type. For gRPC (Google’s RPC framework), the compiler generates:
- Client stub: code that lets you call
GetUserorCreateUserlike local functions. - Server interface: definitions you implement on the server to handle incoming RPC calls.
Compatibility and workflow
Think of the .proto file as the contract between frontend and backend. To keep this magic working, you must follow these rules:
- Never change a field number: If
nameis field1, it must be1forever. - Never reuse a deleted field number: If you delete field
2, do not add a new field with number2. (Use thereservedkeyword to prevent this). - Renaming is fine: You can rename
string name = 1;tostring full_name = 1;. It only cares about the number1.
This enables “Contract-First Development,” where the .proto file is defined before writing any logic. By generating TypeScript interfaces immediately, the frontend team can build UI components using mock data typed against the contract while the backend team works in parallel. This eliminates dependencies, as the code compiler guarantees that the eventual backend response will match the frontend’s expectations perfectly.
Generating code from .proto files
brew install protobuf
protoc --version

# or manually install
sudo cp ~/Downloads/protoc-33.0-osx-aarch_64/bin/protoc /usr/local/bin

# --js_out=... -> Tells protoc to generate JavaScript code
# import_style=commonjs,binary -> Options controlling how JS is generated
# :./src/generated -> Output directory
# src/proto/user.proto	-> Your source .proto file
protoc --js_out=import_style=commonjs,binary:./src/generated src/proto/user.proto

# protoc-gen-js: program not found or is not executable
# https://github.com/protocolbuffers/protobuf-javascript/issues/127#issuecomment-1204202844

# Generate *.ts source files for the given *.proto types
npm install ts-proto

protoc \
    --plugin="./node_modules/.bin/protoc-gen-ts_proto" \
    --ts_proto_opt=esModuleInterop=true \
    --ts_proto_out="./src/generated" \
    src/proto/user.proto
Let’s build a realistic complete example that includes both messages and a service.
syntax = "proto3";

import "google/protobuf/empty.proto";
// Defines namespace "example"
package example;

// --- Messages ---
message GetUserRequest {
  int32 id = 1;
}

message User {
  int32 id = 1;
  string name = 2;
}

message ListUsersResponse {
  repeated User users = 1;
}

// --- Service ---
service UserService {
  rpc GetUser(GetUserRequest) returns (User);
  rpc ListUsers(google.protobuf.Empty) returns (ListUsersResponse);
}
The generated code will include:
- TypeScript interfaces for all messages (
User,GetUserRequest, etc.) - A ready-to-use
UserServiceClientImplclass (for gRPC-Web) - Encode/decode/fromJSON/toJSON helpers
If your backend exposes protobuf over HTTP (not gRPC):
import { GetUserRequest, User } from "../generated/user";

// create a request message
const req: GetUserRequest = { id: 1 };

// serialize to binary
const bytes = GetUserRequest.encode(req).finish();

// send request
const response = await fetch("/api/user/get", {
  method: "POST",
  headers: { "Content-Type": "application/x-protobuf" },
  body: bytes,
});

// receive and decode
const buffer = new Uint8Array(await response.arrayBuffer());
const user = User.decode(buffer);

console.log(user.name);
If you use gRPC (or gRPC-Web on the frontend), the client and server handle that serialization, framing, and transport layer for you. So you no longer use fetch() manually.
import { UserServiceClientImpl } from "../generated/user";
import { GetUserRequest } from "../generated/user";

const client = new UserServiceClientImpl({
  baseUrl: "https://api.example.com",
});

const request: GetUserRequest = { id: 1 };
const response = await client.GetUser(request);

console.log(response.name);
With traditional HTTP/REST APIs, you call a URL and get a response. With RPC, you call a function and get a response.
Don’t think about HTTP/REST implementation details. You call functions, and the RPC framework takes care of everything else. You should ignore details like HTTP Verbs, since they carry meaning in REST APIs, but in RPC form part of your function names instead, for instance:
getUser(id)instead ofGET /users/:id.
Using Protobuf schemas with JSON
In many production systems, .proto files are still used as schemas, but the actual data exchanged is JSON, not binary. It’s easier to debug and inspect over HTTP.
Your codebase likely has generated serialize and deserialize methods for each message type. They map between field names and short tags like {A: ..., B: ...}, which correspond to the field numbers in your .proto file. You can check src/services/foo/bar_proto.ts, the comment in /_ ... _/ shows the JSON key.
- Those letters correspond to field numbers, encoded deterministically by the generator to make JSON smaller and avoid name collisions.
- The backend never depends on “name” or “id” directly — only on the tag numbers defined in your
.protofile.
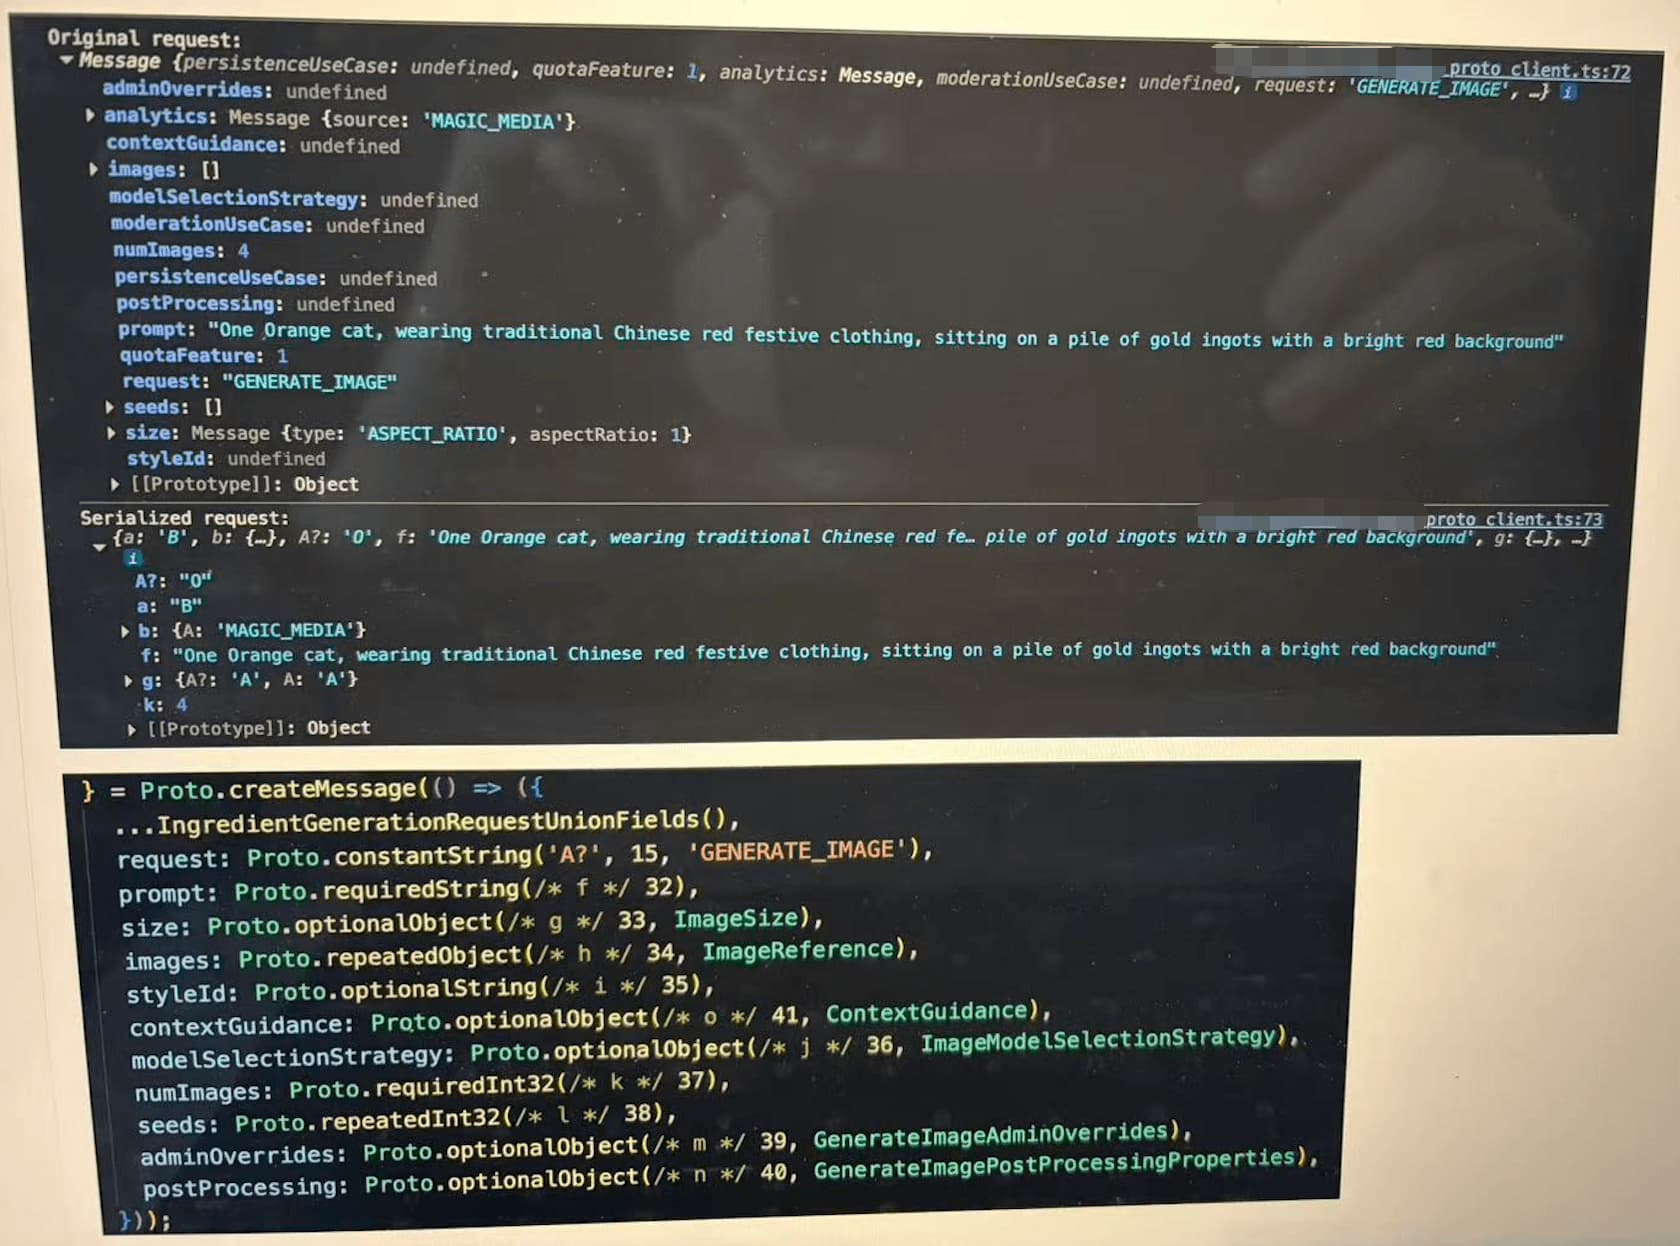
This compact JSON format isn’t limited to APIs. In SSR or hybrid systems, the backend embeds a bootstrap variable directly into the HTML. That variable is a serialized Protobuf message, but encoded as JSON. The frontend needs to deserialize it to restore the same typed data structures that the backend used.
Protobuf and gRPC
gRPC is a high-performance communication framework like REST, but more efficient and strongly typed. It allows one program (like your frontend) to call a function that actually runs on another computer (like your backend), almost as if it were a local call.
gRPC has two sides: a server side, and a client side that is able to dial a server. The server exposes RPCs (i.e. functions that you can call remotely). gRPC uses protobuf as its wire format and API contract. When you combine them, code generators produce client and server stubs that handle serialization/deserialization and network communication automatically.
For example:
// looks like a local function call...
const user = await getUser({ id: 123 });
But behind the scenes, this does much more:
- The frontend serializes
{ id: 123 }into a binary protobuf message. - It sends that message over the network (using HTTP/2 or gRPC-Web).
- The backend receives and deserializes it into a
GetUserRequestobject. - The backend executes the
GetUserfunction. - The backend returns a serialized protobuf response (
User) back to the client. - The client deserializes that binary data into a usable TypeScript object.
Normal gRPC (used by backend-to-backend communication) runs over HTTP/2. Browsers can’t fully control HTTP/2 like servers can. That means you can’t directly call a gRPC service from browser JavaScript using fetch() or XMLHttpRequest. To bridge this gap, gRPC-Web provides a browser-compatible variant of gRPC that wraps the same protobuf messages in a simplified wire format browsers can handle.